Who does AI send US buyers to this week?
Every week we ask ChatGPT and Gemini the same buying questions and count the brands in their answers. In every category, a small set of brands dominates — and the table barely moves from week to week.
Loading…
Loading data…
Method: 100 questions, 10 buyer profiles, ChatGPT and Gemini, web search on, same questions every week.
So far we have run the 100 air fryer questions twice on the same day on two occasions. With the earlier ChatGPT model (October 4) the top five brand rates moved by 2 points on average (3 at most). With the current models (October 25) they moved by 3.4 points on average (9 at most). Week-to-week changes under 10 points are treated as noise.
As of week 4 we count the first three distinct brands in each answer; all previous weeks were recomputed with the same rule. Earlier published figures differ, in a few cases by more than 10 points.
New categories (from October 14): 50 questions each, five buyer situations, every question asks for specific models. In a separate 50-answer rice-cooker same-day rerun using the Sunday format and the previous ChatGPT model, brand rates moved by up to 10 points. This is context only, not a repeatability estimate for the new categories; no trend is inferred from their first week. In travel bags and hair tools the product asked about changes with the buyer situation, so results there are shown per situation.
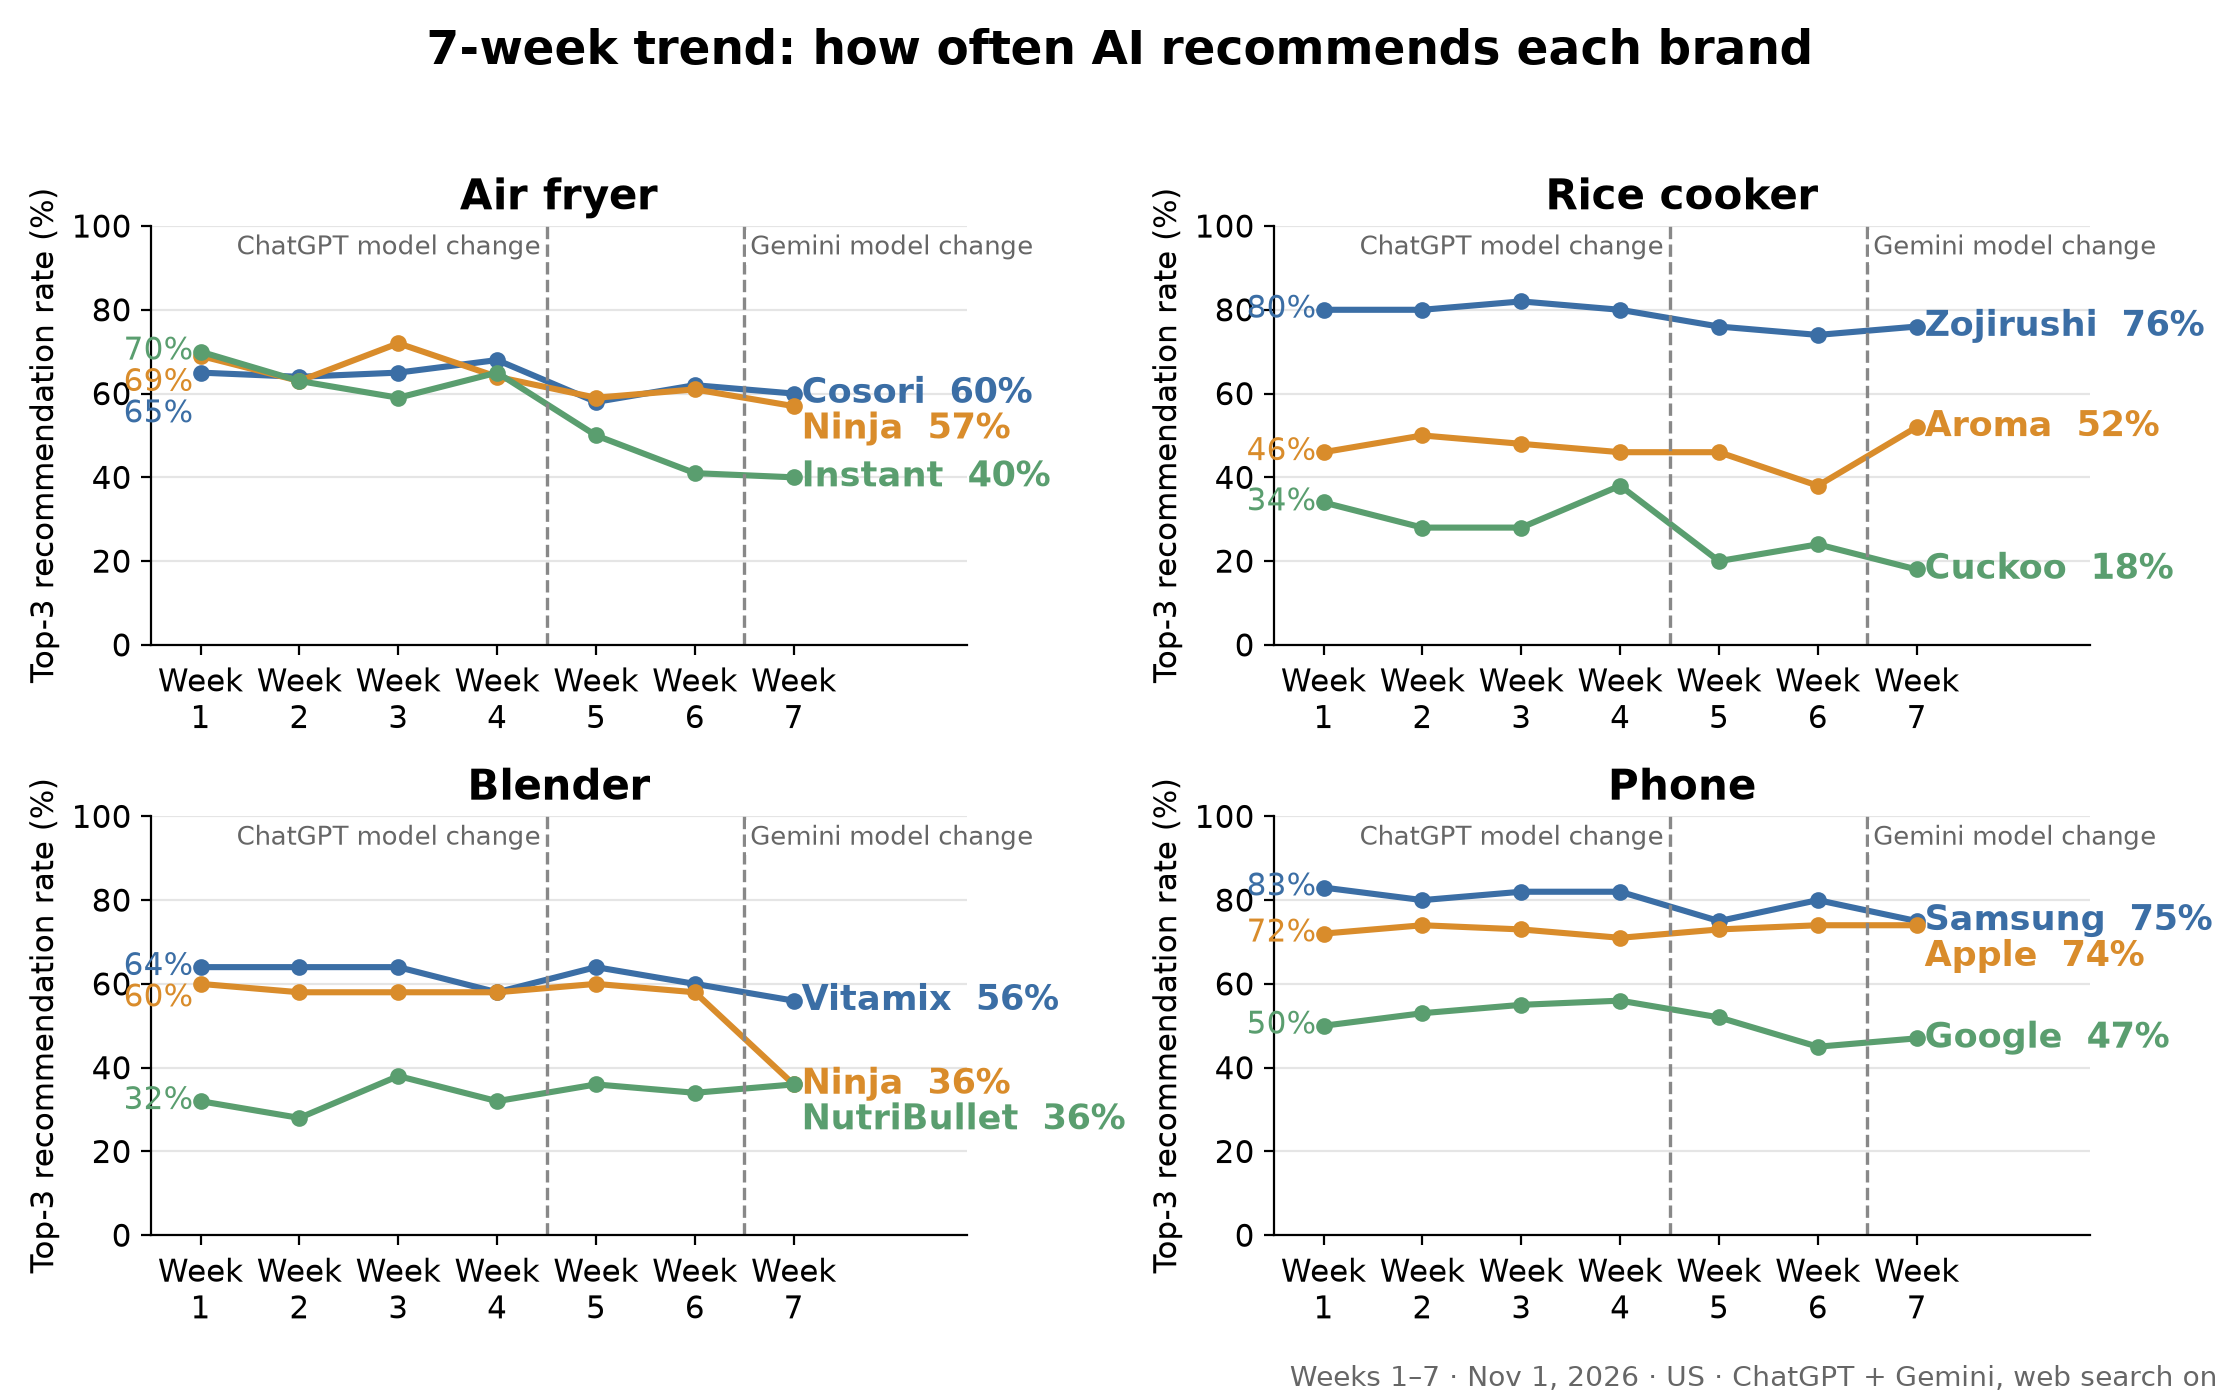
Models: We use the API model closest to each app's free default. ChatGPT side: weeks 1–4 gpt-5.6-luna; ChatGPT's free default moved to GPT-6 Luna on Oct 8, so week 4 (Oct 11) was still measured with the older model. From week 5 (Oct 18) the weekly series uses gpt-6-luna; the dashed line in the trend chart marks the switch. In week 5 we also ran the same ChatGPT questions on gpt-5.6-luna on the same day as a bridge; that run is not mixed into the series. On ChatGPT's answers alone, the largest bridge gaps (new minus old model) were: air fryer, Instant −28 and Cosori −16 points (50 answers per model); phone, Samsung −16 (50); rice cooker, Cuckoo −24 and Tiger −20 (25); blender, Blendtec −16 and Oster −16 (25). With 25 answers one answer is 4 points, so the rice cooker and blender gaps are rough. Week-5 changes for those brands cannot be read as pure week-to-week movement, because the model changed at the same boundary. The new categories use gpt-6-luna from their first week. Gemini side: weeks 1–6 gemini-3.6-flash. Since Oct 9 the Gemini app's free default has been Auto, which Google says sends most prompts to Flash-Lite; the help page names no version, so we use the newest Flash-Lite in the API. Weeks 4–6 (Oct 11–25) were still measured with the older model. From week 7 (Nov 1) the weekly series uses gemini-3.5-flash-lite; the second dashed line in the trend chart marks the switch. In week 7 we also ran the same Gemini questions on gemini-3.6-flash on the same day as a bridge; that run is not mixed into the series. On Gemini's answers alone, the largest bridge gaps (new minus old model) were: air fryer, Instant −16 points (50 answers per model); phone, OnePlus −12 (50); rice cooker, Tiger −32 (25); blender, Ninja −36, Magic Bullet +28, Oster −20 and NutriBullet +16 (25). Week-7 changes for those brands cannot be read as pure week-to-week movement, because the model changed at the same boundary. The Wednesday categories and the one-time categories measured through Oct 28 used gemini-3.6-flash; the one-time categories measured on Nov 4, including the second cookware reading, use gemini-3.5-flash-lite.
Models: We use the API model closest to each app's free default. ChatGPT side: weeks 1–4 gpt-5.6-luna; ChatGPT's free default moved to GPT-6 Luna on Oct 8, so week 4 (Oct 11) was still measured with the older model. From week 5 (Oct 18) the weekly series uses gpt-6-luna; the dashed line in the trend chart marks the switch. In week 5 we also ran the same ChatGPT questions on gpt-5.6-luna on the same day as a bridge; that run is not mixed into the series. On ChatGPT's answers alone, the largest bridge gaps (new minus old model) were: air fryer, Instant −28 and Cosori −16 points (50 answers per model); phone, Samsung −16 (50); rice cooker, Cuckoo −24 and Tiger −20 (25); blender, Blendtec −16 and Oster −16 (25). With 25 answers one answer is 4 points, so the rice cooker and blender gaps are rough. Week-5 changes for those brands cannot be read as pure week-to-week movement, because the model changed at the same boundary. The new categories use gpt-6-luna from their first week. Gemini side: weeks 1–6 gemini-3.6-flash. Since Oct 9 the Gemini app's free default has been Auto, which Google says sends most prompts to Flash-Lite; the help page names no version, so we use the newest Flash-Lite in the API. Weeks 4–6 (Oct 11–25) were still measured with the older model. From week 7 (Nov 1) the weekly series uses gemini-3.5-flash-lite; the second dashed line in the trend chart marks the switch. In week 7 we also ran the same Gemini questions on gemini-3.6-flash on the same day as a bridge; that run is not mixed into the series. On Gemini's answers alone, the largest bridge gaps (new minus old model) were: air fryer, Instant −16 points (50 answers per model); phone, OnePlus −12 (50); rice cooker, Tiger −32 (25); blender, Ninja −36, Magic Bullet +28, Oster −20 and NutriBullet +16 (25). Week-7 changes for those brands cannot be read as pure week-to-week movement, because the model changed at the same boundary. The Wednesday categories and the one-time categories measured through Oct 28 used gemini-3.6-flash; the one-time categories measured on Nov 4, including the second cookware reading, use gemini-3.5-flash-lite.